In Part 1 we built the setup that a lot of fleets actually run. A device pulls short lived AWS credentials with its certificate through the IoT Credentials Provider, and behind that sits an IAM role that is allowed far too much. We watched the legitimate path work. station-07 pulled credentials, wrote into its own prefix, and everything looked correct. Then we stopped, right at the moment where it stops being correct.
Now we break it. This post takes over one station and follows the attacker step by step, and then spends most of its length on the part that matters more than the commands: why it worked at all.
The break-in we assume
We don't spend time on how the attacker gets onto the device. Picture one of those pressure reduction stations. It sits in a cabinet at the edge of a field, reachable over a maintenance network, sometimes reachable by anyone who can open a door. Assume the attacker is already on the Pi. That is the realistic starting point for edge hardware, and it is not the interesting part.
What matters is what the attacker walks away with. It is exactly what sits on the device: the certificate and its private key under ~/certs/. No console access. No static keys. No IAM permissions. Just the same certificate the device uses every day.
From here everything runs on the device, using only credentials pulled with that certificate. The attacker asks the Credentials Provider for a session, the same way the real workload does, and gets back an assumed role identity tied to the device.
aws sts get-caller-identity"Arn": "arn:aws:sts::<account-id>:assumed-role/iot-lab-device-role/<cert-id>"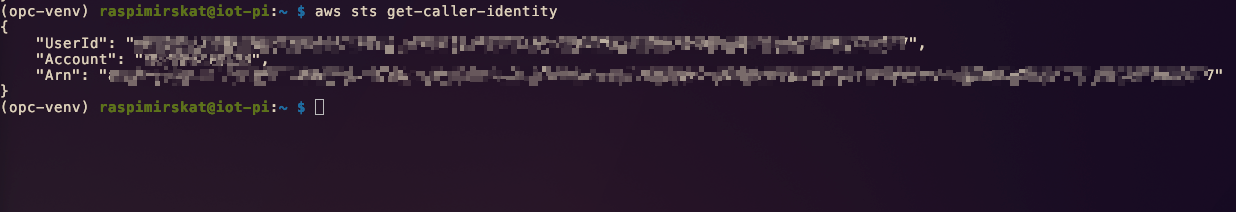
That is the attacker now. Not a person, not an admin, just station-07 being station-07. Every command from here uses that identity.
Recon: what can this one device see
The first move is always to look around. The role allows listing, so the attacker lists.
aws s3 ls
aws s3 ls s3://iot-lab-data-<account-id> --recursive
And there is the first problem, in plain sight. station-07 does not just see its own data. It sees the whole data lake. Its own prefix, the other station, the shared configuration, the firmware image.
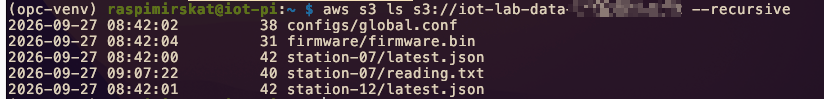
One compromised station now has a map of the entire fleet. It knows the other stations exist, it knows where the shared config lives, and it knows where firmware comes from. Nothing has been broken yet. The attacker is simply reading what this identity was allowed to read all along.
Reading a neighbor's data
station-07 has no operational reason to touch station-12. It does anyway.
aws s3 cp s3://iot-lab-data-<account-id>/station-12/latest.json -
aws s3 cp s3://iot-lab-data-<account-id>/configs/global.conf -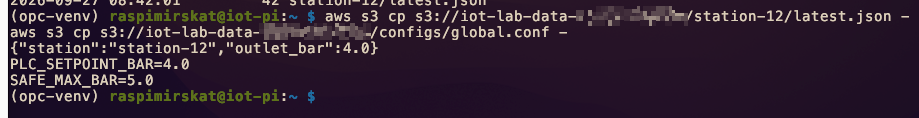
The attacker reads a foreign station's process data and the shared plant configuration, including the setpoints and the safety limit. This is already a fleet wide confidentiality breach from a single foothold. In a real environment this is where an attacker learns the shape of the plant: how many stations, what the normal values look like, where the safety envelope sits.
Rewriting what the fleet trusts
Reading is the small version. The role also allows writing to objects that belong to other devices, and that is where a single compromise turns into a fleet problem. The valuable targets are not the other stations directly. They are the files every device reads back on its own: the shared configuration and the firmware image.
Move the safety envelope first.
printf 'PLC_SETPOINT_BAR=4.0\nSAFE_MAX_BAR=9.9\n' > evil.conf
aws s3 cp evil.conf s3://iot-lab-data-<account-id>/configs/global.conf
SAFE_MAX_BAR just went from 5.0 to 9.9. That is the exact limit that raised the overpressure alarm in the first article. Any device that reloads this config now believes that almost twice the pressure is still inside safe bounds.
Then replace the firmware that the whole fleet pulls.
printf 'backdoored-firmware\n' > evil.bin
aws s3 cp evil.bin s3://iot-lab-data-<account-id>/firmware/firmware.bin
This is the whole attack in two commands, and it is worth being precise about what just happened. The attacker did not touch station-12. The attacker did not open a single new connection to any other device. It changed two files in a bucket, and then walked away.
Why this is a supply chain attack
The data lake is not only storage. It is a distribution point. Configuration and firmware sit there centrally, and every station pulls from there on its next update. That single fact is what turns one compromised device into a fleet wide compromise.
The attacker never has to reach the other stations. The regular update process does it for them. At the next update window every station pulls the poisoned config and the poisoned firmware from the source it has always trusted, and applies it. The trusted update channel carries the attack the last mile.
Three properties make this class of attack so effective...
It uses the legitimate path. The stations do exactly what they are supposed to do, which is fetch updates from the central location. There is no exploit on the target stations, no unusual traffic, nothing that looks like an intrusion. It looks like a normal rollout.
It is delayed in time. The gap between poisoning the source and the next update window can be long. When station-12 later behaves incorrectly, the incident on station-07 is already old news. The two events look unrelated, which is precisely what makes the root cause hard to find.
It works in two stages. The poisoned config shifts the safety limits the moment it is reloaded. The poisoned firmware establishes something durable that survives a config cleanup. Fixing the obvious symptom does not remove the deeper foothold.
This is the SolarWinds pattern, moved into an OT context. Compromise the source everyone trusts, and let the trusted process distribute the result. In the enterprise world the source was a build server. Here it is an S3 prefix that one field device is allowed to overwrite.
The blast radius does not stop at the lake
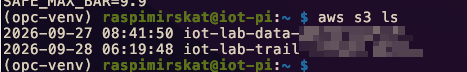
There is one more property worth stating, because it shows the scope of the underlying flaw. The role does not grant access to one bucket. It grants access to every object in the account.
aws s3 lsEvery bucket this returns is reachable with the same credentials. Backups, logs, exports, anything else in the account. The data lake was the interesting target for this story, but it was never the boundary. The boundary was the role, and the role had none.
Why it worked
Now the part that matters more than the commands. Nothing above was a broken feature. Every step used AWS exactly as designed. So it is worth walking through the chain and naming the point where it actually failed.
The certificate did its job. Mutual TLS proved that this was a valid device, and it was. The device was not spoofed. The identity was real.
The Credentials Provider did its job. It saw a valid certificate, matched it to the role alias, and handed back short lived credentials. This is the recommended pattern, and using it was correct. No static keys ever touched the device.
The IoT policy did its job. It granted the one action needed to request credentials, iot:AssumeRoleWithCertificate, and nothing more. That grant is intended and part of normal operation.
Every link in the chain behaved correctly. And the attacker still reached the whole fleet. That is the point of the entire post. The failure was not in authentication and not in the mechanism. The failure was in authorization, specifically in the scope of the role that the mechanism handed out.
Two decisions inside that role did the damage...
The first is that every station assumes the same role. There is one iot-lab-device-role, and station-07, station-12 and every future station share it. The moment a role is shared across a fleet, the identity of the individual device stops meaning anything at the permission layer. The credentials say station-07, but the permissions say fleet. Authentication kept the devices apart. Authorization put them back in one bucket.
The second is the resource. The role allows its actions on Resource: "*". Nothing ties a device to its own station. A version of this role scoped with s3:GetObject on the whole bucket instead of a single prefix would be the same class of mistake. The wildcard on the action is loud and easy to spot in a review. The missing restriction on the resource is quiet, and it is the one that actually let station-07 read and rewrite station-12.
Put together, the device authenticated as exactly one station and was then authorized as all of them. The certificate was never the security boundary. In the first article the IoT policy was the boundary. Here, one layer deeper, the IAM role is the boundary. And a boundary set to "*" is not a boundary. It is the whole account.
There is a reason this specific shape is so common. s3:* on * makes the device work immediately. Every upload succeeds, every download succeeds, nothing fails during development, and the role quietly ships. It is the IAM version of the same convenience that produced the iot:* policy in Part 1. It works on the first try, and it keeps working right up until one device is copied.
Flipping the fix on
Applying it is a single call, because the broad grant was an inline policy on the role. We replace it in place.
{
  "Version": "2026-09-28",
  "Statement": [
    {
      "Sid": "OwnPrefixObjects",
      "Effect": "Allow",
      "Action": ["s3:GetObject", "s3:PutObject"],
      "Resource": "arn:aws:s3:::iot-lab-data-767397776192/${credentials-iot:ThingName}/*"
    },
    {
      "Sid": "ListOwnPrefixOnly",
      "Effect": "Allow",
      "Action": "s3:ListBucket",
      "Resource": "arn:aws:s3:::iot-lab-data-767397776192",
      "Condition": {
        "StringLike": { "s3:prefix": "${credentials-iot:ThingName}/*" }
      }
    },
    {
      "Sid": "ReadSharedArtifactsOnly",
      "Effect": "Allow",
      "Action": "s3:GetObject",
      "Resource": [
        "arn:aws:s3:::iot-lab-data-767397776192/configs/*",
        "arn:aws:s3:::iot-lab-data-767397776192/firmware/*"
      ]
    }
  ]
}
Nothing on the device changes. Same certificate, same role alias, same Credentials Provider call. The device does not even know its permissions shrank. That is the point. The fix lives entirely on the cloud side, on the object that was too permissive in the first place.
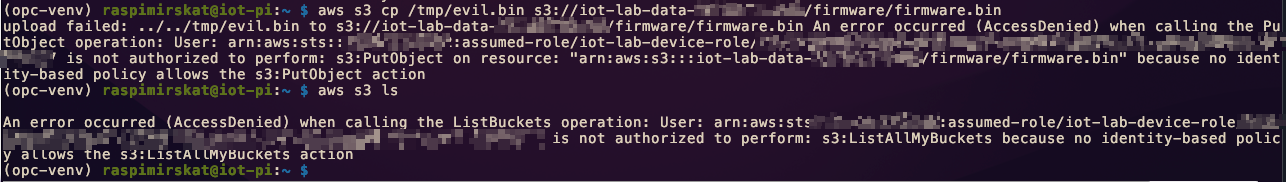
Recon is already dead. Listing the whole lake, the first move the attacker made, now returns nothing it is allowed to see.
And the step that turned one compromise into a fleet compromise no longer runs at all.
Same device, same certificate, same session, same commands. The attacker is now boxed into exactly one prefix, the one that belongs to the station they already own. The lateral movement is gone, because the identity that used to mean nothing at the permission layer now means everything.

What the fix stops, and what it does not
It would not be honest to end on a clean win without naming the limits, because scoping the role does not make the station safe. It makes the blast radius match the compromise.
It stops lateral movement in the data plane. A compromised device can no longer read or write another device's data, and it can no longer touch the shared distribution point. The account is no longer the blast radius. One prefix is.
It does not protect a device from itself. Whoever owns station-07 can still lie about station-07. They can publish false telemetry for their own station and write junk into their own prefix. Scoping contains the damage to one station. It does not remove it. The answer to that is not IAM, it is validation and anomaly detection on the values themselves.
It does not help if the certificate keeps working after the device is known to be compromised. The moment you know a station is owned, the certificate has to be revoked and the thing detached, or the attacker simply keeps pulling fresh credentials for their one prefix forever. Scoping limits what those credentials can do. Revocation is what finally turns them off.
And it does not replace detection. A device confined to its own prefix that suddenly starts hammering that prefix, or pulling firmware in a loop, is still worth an alert. Prevention shrinks what an attacker can reach. It does not tell you when someone is trying.
But is this not what Greengrass and SiteWise are for?
SiteWise is the wrong tool for this part anyway, since its job is ingesting and modeling industrial telemetry, not pushing config or firmware to devices. Greengrass is the right tool, and for serious fleet distribution you use its deployments with versioned components and rollback instead of a bucket layout you maintain by hand.
But Greengrass does not remove the flaw. It stands on the same mechanism. A core device gets its AWS credentials through the token exchange service, which uses an IoT role alias pointing to an IAM token exchange role, assumed through the same certificate based credentials provider. If that role is scoped to s3: on , one compromised core device reaches the whole fleet in exactly the same way, only with a product name in front of it. The boundary is still the IAM role. We use the raw S3 pattern here because it is the smallest setup that shows that boundary, and because plenty of real fleets run bare MQTT devices that pull from S3 exactly like this.
Closing thoughts
The whole three part arc lands on one sentence. Authentication proves who a device is. Authorization decides how much of your world that device can touch. In Part 1 the boundary was the IoT policy. Here, one layer down, it was the IAM role. Both times the mechanism was sound and the scope was the flaw, and both times the fix was the same shape: bind the permission to the single identity that earned it, and to nothing else.
The convenient version, iot:* or s3:* on *, works on the first try and keeps working until one device is copied. The scoped version takes an afternoon to get right, mostly because you have to make identity and layout agree first. After that, a stolen certificate buys an attacker exactly one station, which is the most a stolen certificate should ever buy.